Real presenters work the same way
Filmed footage takes the same captions, name tags and screen inserts: here a presenter on one half and the live website build on the other.
See the split-screen explainerGive JsonCut a portrait and a voice track. Fabric 1.0 or Aurora turns it into a speaking presenter, up to 60 seconds, ready for captions, graphics and music on the same timeline.
Real sample frames from each model, as Studio shows them in the model picker.
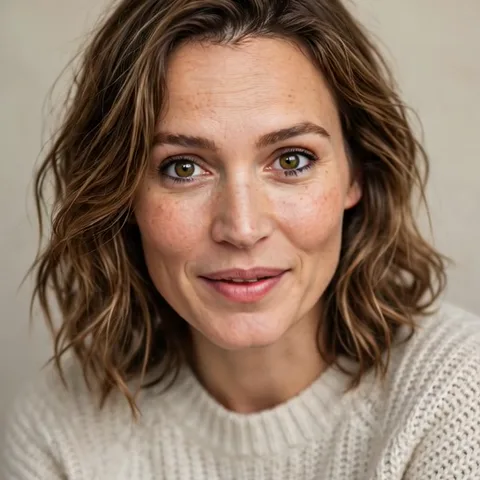
A portrait speaks your voice track with natural lip-sync
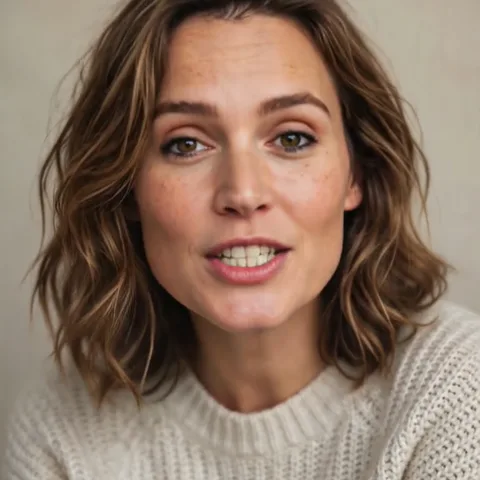
Expressive talking heads with gestures
A photo you own, or one you generate with any of the twelve image models in the same project.
Type a script and pick one of 21 voices, or use a recording. The take follows the voice track word for word.
Word-timed captions, a name tag, b-roll and music go on top as editable layers. Change one word without generating again.
Filmed footage takes the same captions, name tags and screen inserts: here a presenter on one half and the live website build on the other.
See the split-screen explainerMara again, now speaking German: the same photo, a German voice in the same tone, lips in sync and German captions timed to every word.
See voiceover and translationYes, any portrait you have the rights to. The model animates the picture; it does not clone a voice. Pick a Studio voice or upload your own recording.
Up to 60 seconds per take, at 480p or 720p. Longer videos are several takes on the timeline, cut between b-roll and graphics.
Building and previewing in Studio is free. AI generation, the AI Director and exports are part of the 14-day trial and the paid plans; credits show the cost before anything runs.